What it does
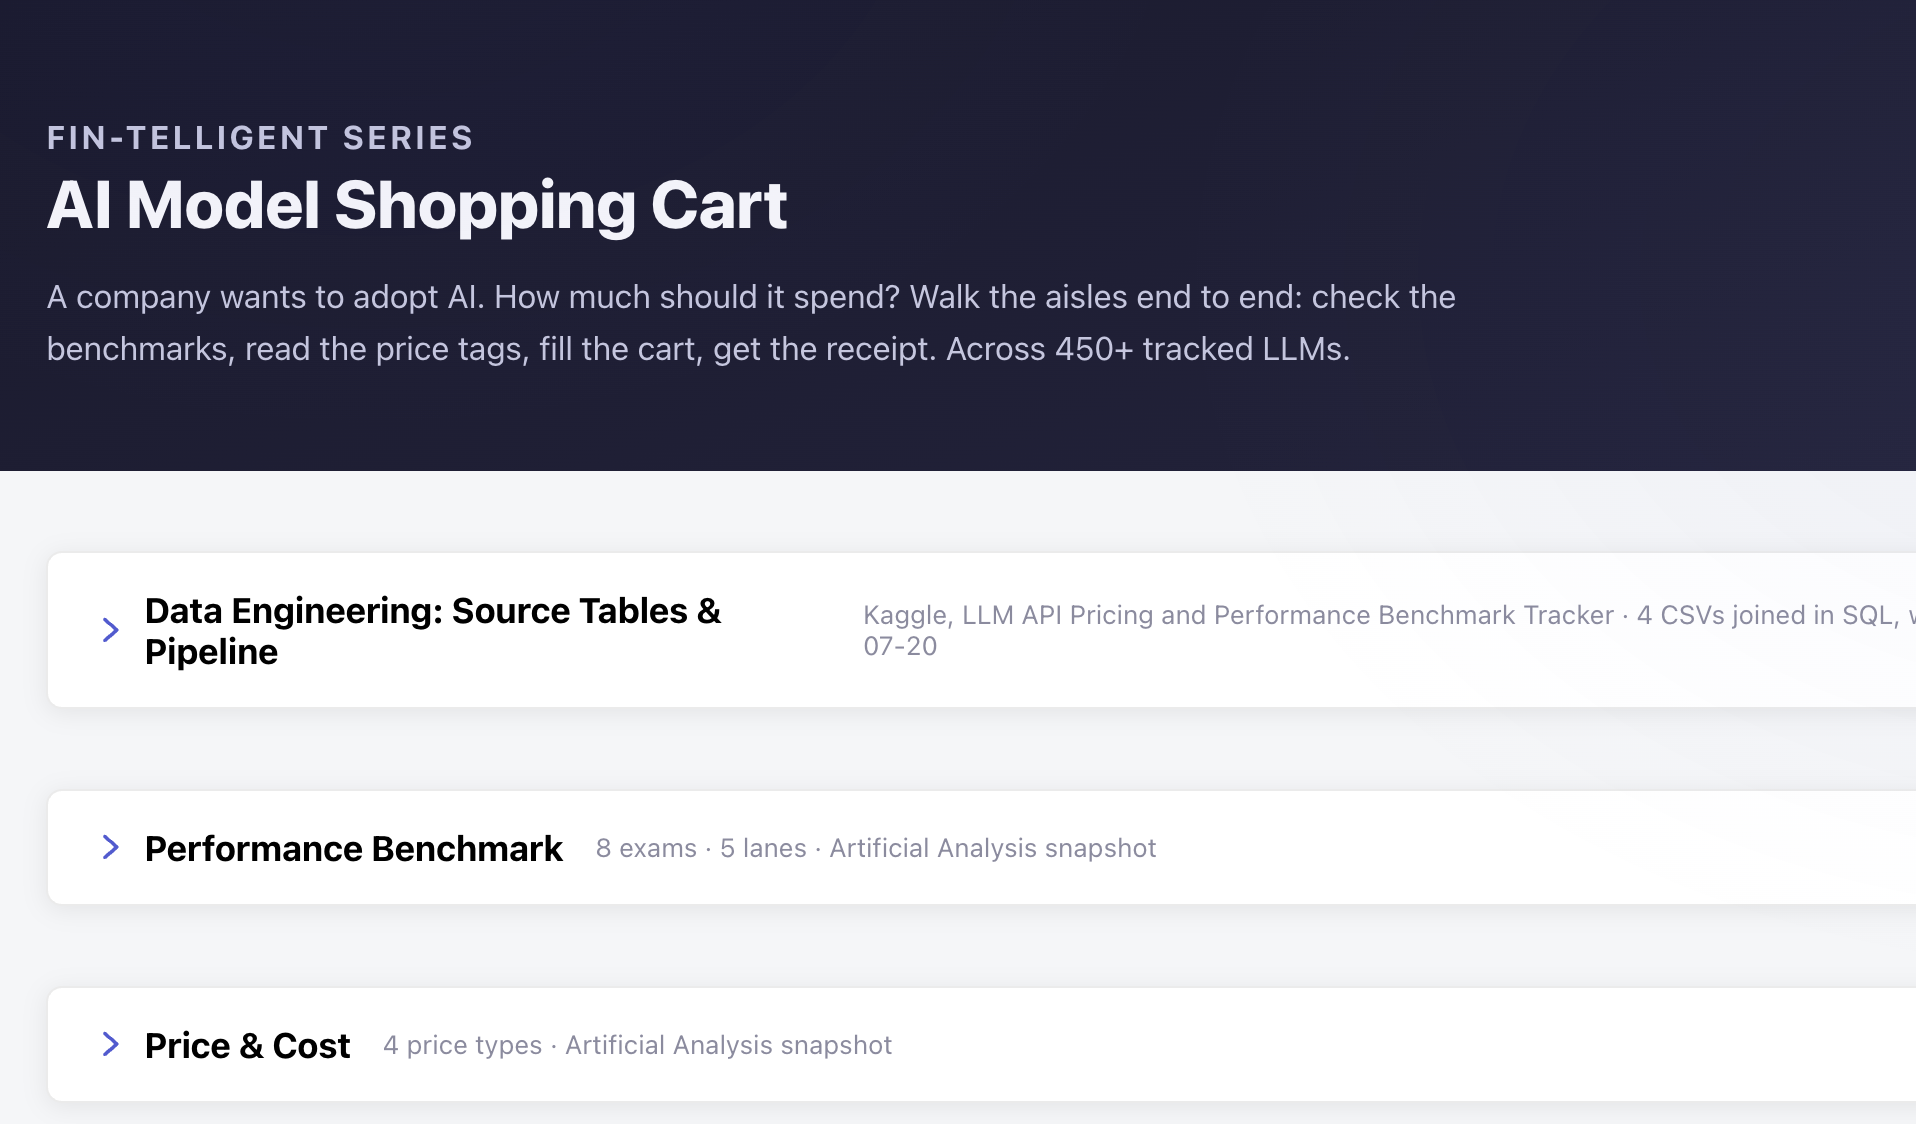
Departments drop into a cart with their team size. Each kind of work (Q&A, document analysis, modeling, coding) maps to a benchmark lane and a price tier, so the cart assembles a model portfolio with a live monthly budget. The logic fits on one line: Total Model Cost = Price × Tokens.
How it works
Benchmarks and prices come from the Artificial Analysis leaderboard. Models are sorted into four price tiers by blended cost; within each tier, picks follow benchmark scores with a response-speed floor. Token usage per person comes from task-level assumptions shown and adjustable on the page.
How we used Nimble
The model shelf changes every few weeks, so a static dataset goes stale fast. A Nimble SDK script extracts the latest models and today's prices, with Search as a fallback, and a GitHub Actions job reruns it daily. The page rebuilds a New Shopping Cart next to Your Cart: models with newer versions get upgraded, the rest are repriced, all under the same rules. Refresh to browse the rest of the shelf.
Liquid AI
LFM2 sits in the value aisle: under $0.10 per million tokens with a first token in about 0.2 seconds, the fast, low-cost pick for high-frequency work.
Finance sets the rules, AI executes.