tokens&
BrowseFor enterprises
tokens&

Find tools, check provider offers, save a build plan, and share your work when you’re ready.

For buildersFor enterprises

For builders

  • Startup credits and perks
  • Agent Skills
  • Publish a project

For enterprises

  • Start free company workspace
  • Submit a tool, product, or perk

Community

  • Community
  • Newsletter
  • Events
Xin

© 2026 tokensand, LLC. All rights reserved.

  • Terms
  • Privacy
  • Security
  • Data Processing
  • Status
  1. Hackathon
  2. Project gallery
  3. Ask Omda
Rachel Lowabout 10 hours agoContributorJudging locked: Event build

Ask Omda

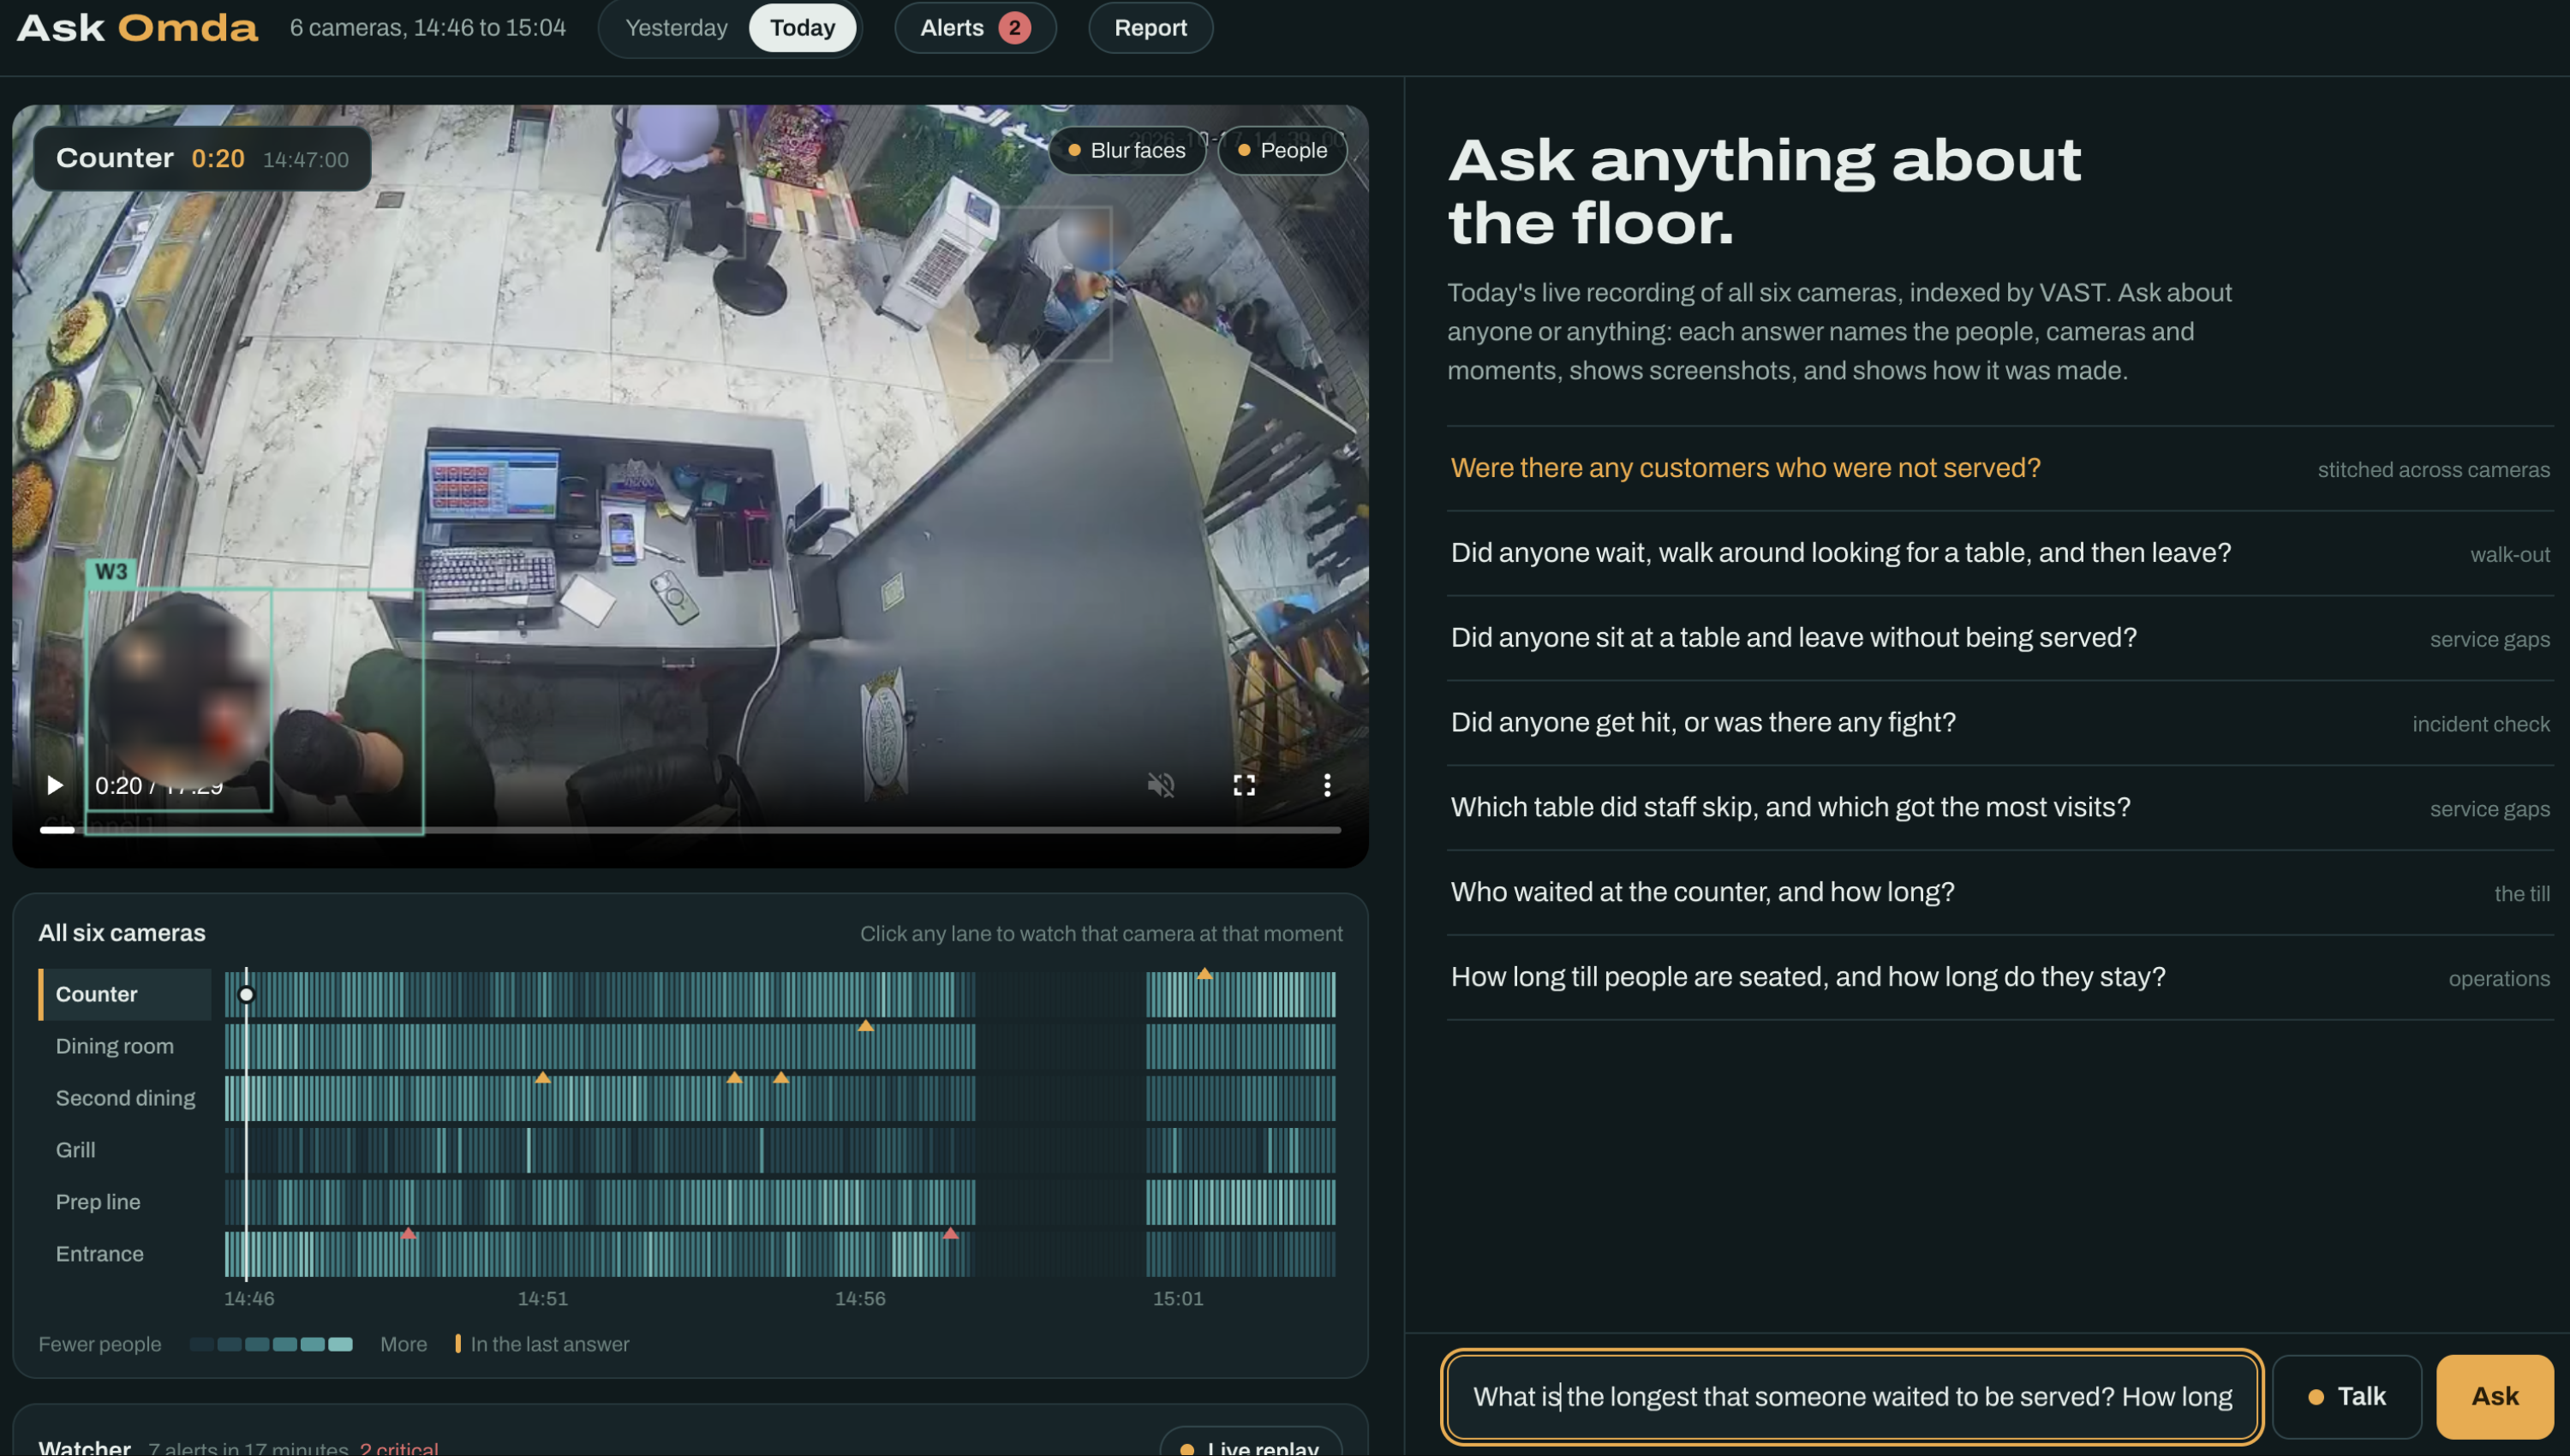
Ask Omda is a floor manager that watched all six cameras of a London restaurant, so you can ask the floor anything, by text or voice, and get the people, the cameras and the exact clips back.

Review the project

Start with the source code, then open the demo or video if available.

View GitHub repository
Visit project website
Demo video
Watch demo video
Project description
Omda is a real restaurant. Friday lunch, six cameras, five minutes, 350 clips nobody has time to watch. Ask Omda answers questions about the floor and cites the moments it used: “Did anyone leave without paying?”, “Deleveroo says rider D6 was late, whose fault was it?”, “What would you flag to the owner?” It works by text or voice over any 5-minute, 30-minute or 1-hour window. It does three things a human can’t do at lunch rush. Dine-and-dash detection: a party finishes, stands and exits; Omda checks the till camera in between and finds no payment. Delivery dispute resolution: a door-to-counter-to-door timeline for every rider, so the kitchen stops eating refunds it didn’t cause. Owner’s briefing: an auto-written report of bottlenecks, waits and anomalies, each point linked to a clip. Every 5-second clip is described by NVIDIA Cosmos Reason, counted by YOLO11 and embedded with Cosmos Embed1, then indexed in VastDB via VAST DataEngine. Our Floor Twin tracker (DGX Spark) gives customers, staff and riders stable IDs, so the agent can stitch one person across rooms and one moment across cameras. Reasoning runs on DeepSeek via W&B Inference; every answer is traced and scored in Weave against ground-truth and adversarial questions, so it cites or says it doesn’t know. Built with Cursor on the VAST workshop skills.
Tools used
  • VAST Data logoVAST Data
  • CoreWeave (Weights & Biases) logoCoreWeave (Weights & Biases)
  • NVIDIA logoNVIDIA
  • SpaceXAI (Cursor) logoSpaceXAI (Cursor)
Watch demo video
Project gallery
Project links
  • GitHub repository
  • Project website
  • Demo video
Tools used
  • VAST Data logoVAST Data
  • CoreWeave (Weights & Biases) logoCoreWeave (Weights & Biases)
  • NVIDIA logoNVIDIA
  • SpaceXAI (Cursor) logoSpaceXAI (Cursor)