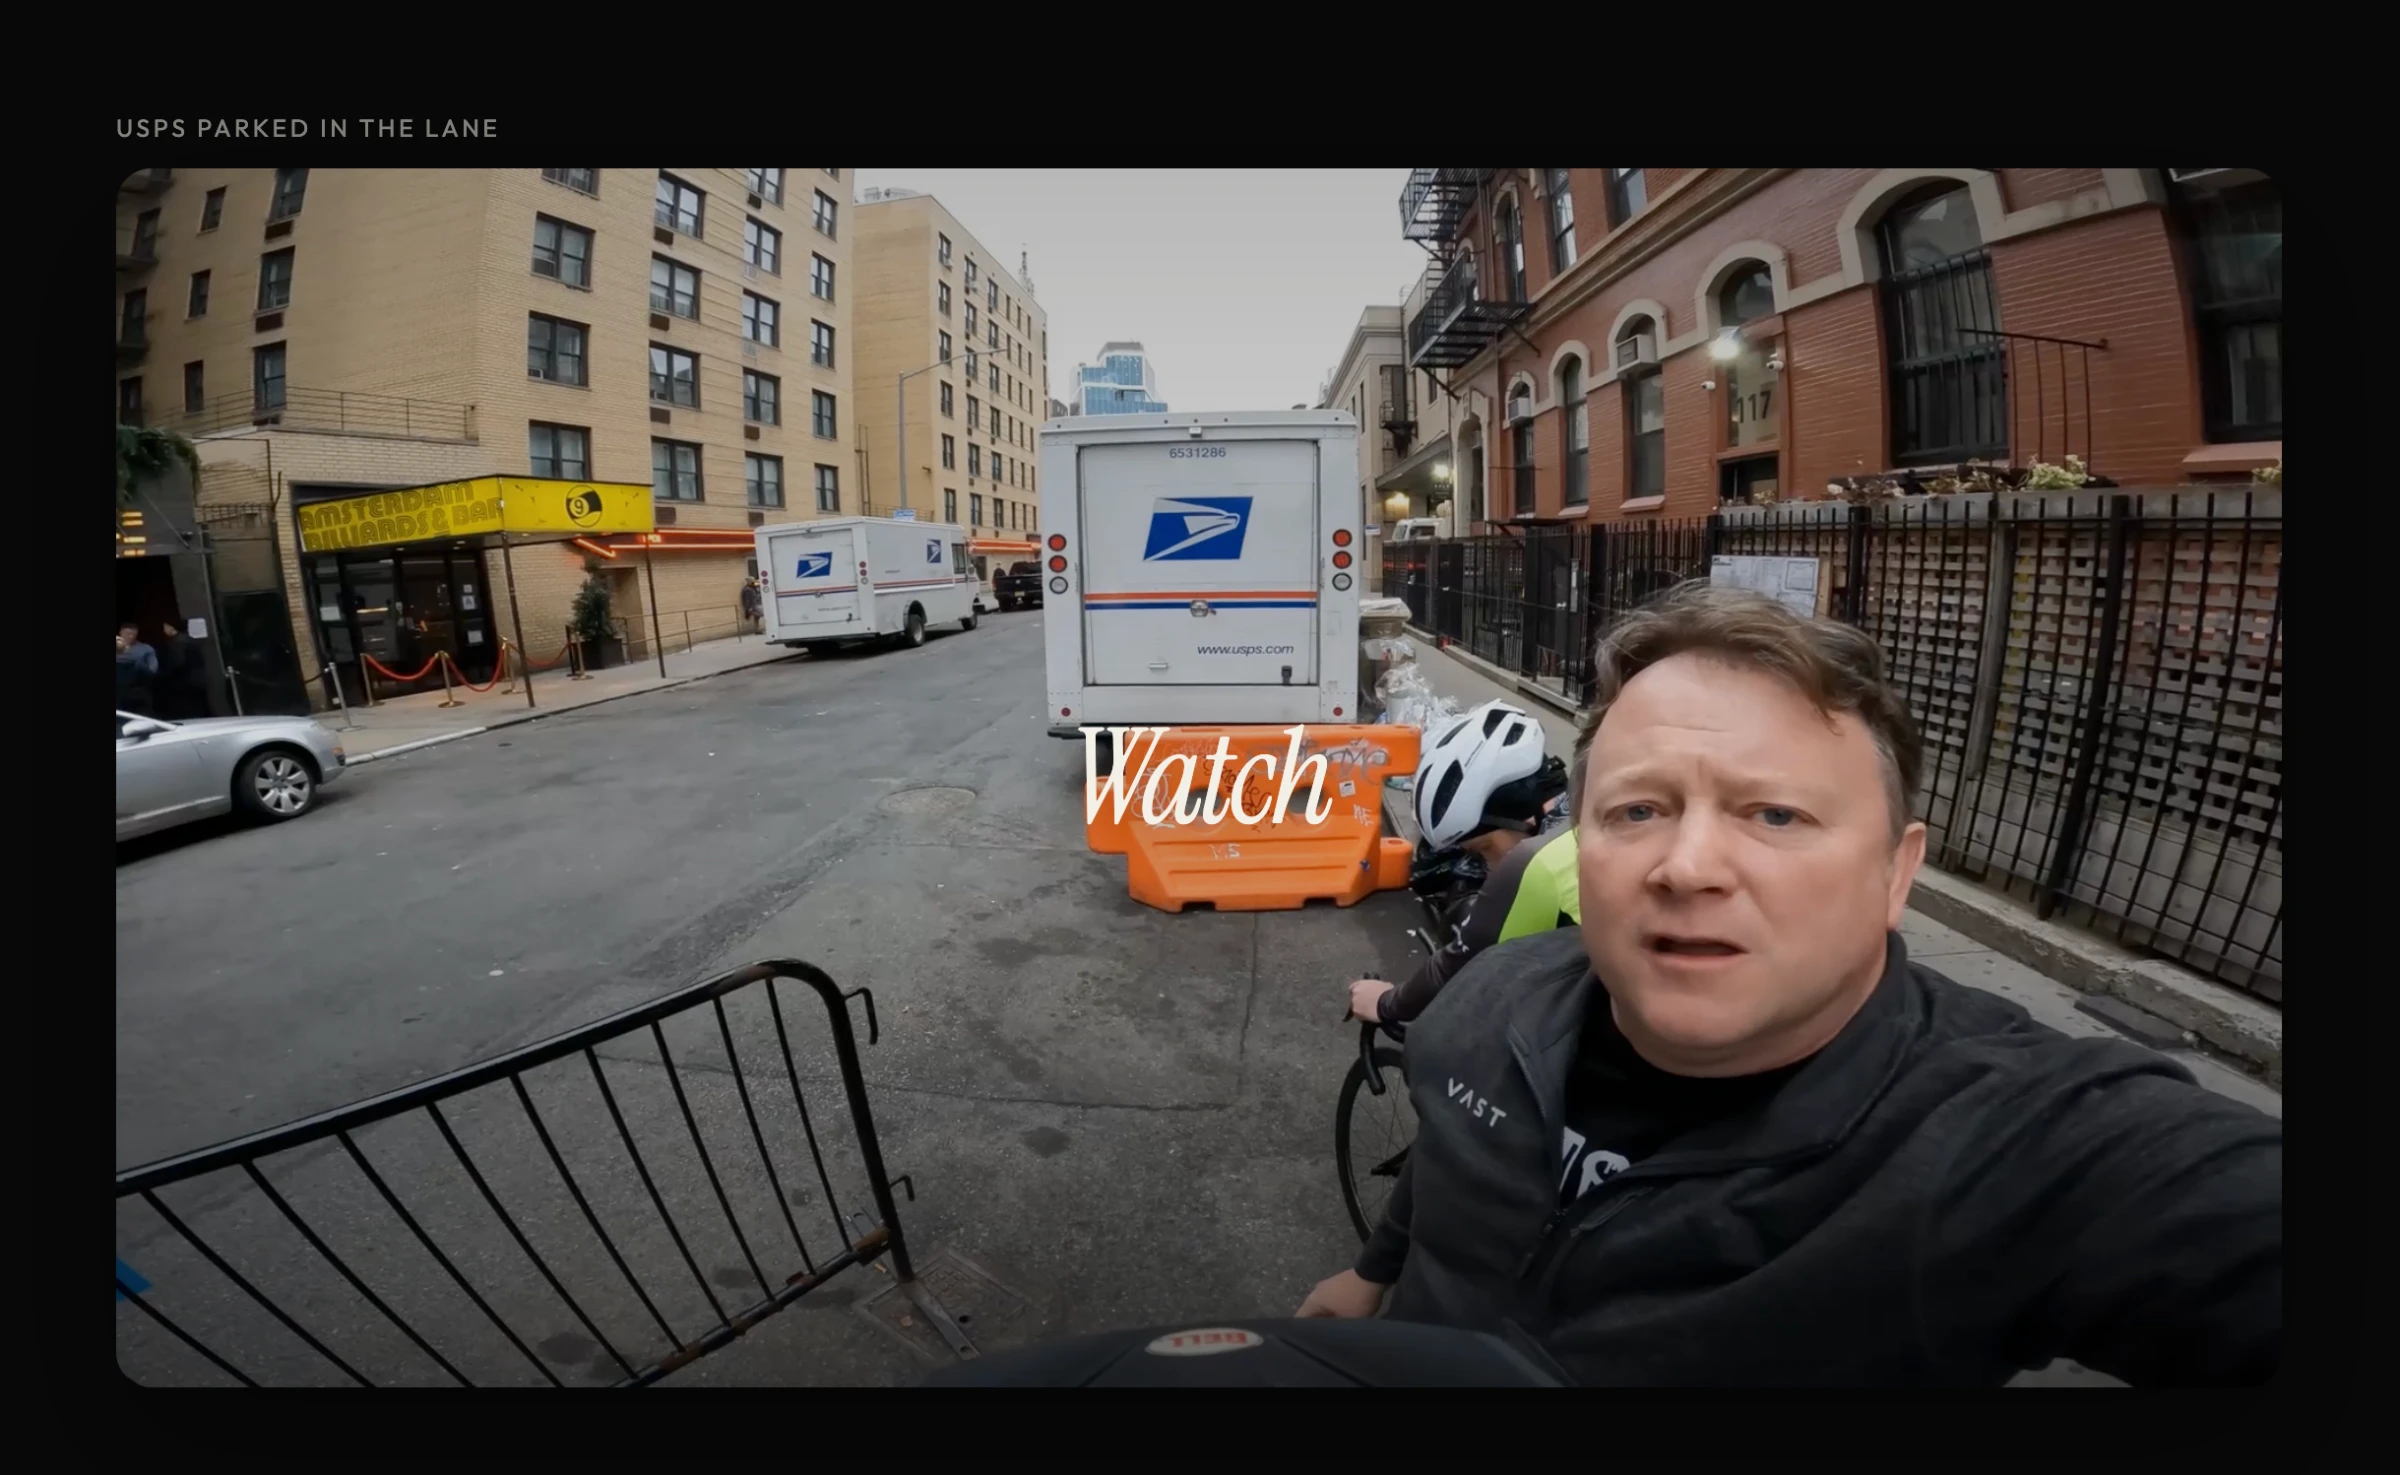
Behind is a short lesson for cyclists and drivers, taken from footage they could have been in.
You press Watch. A New York rider's view, or a San Francisco intersection, plays with nothing drawn on it. When it ends, the street goes black and one light stays on the thing that should change the next move: a person standing in front of a parked mail truck, a truck filling the lane, a rider ahead while a car closes on the right, people in a crosswalk, a car coming through from the right. A voice gives the advice in one line: wait, stay stopped, hold your line, or let it through.
A cyclist can replay the moment they would have squeezed a parked truck or swung out in the dark, and hear the move before they need it. A driver can do the same at a crossing: stay put until the stripes are empty, and do not take a gap that is already closing.
The clips and detection tracks come from VAST: video in VAST S3, indexed by VAST DataEngine into VastDB. Behind only reads that archive. NVIDIA Cosmos Reason and Cosmos Embed, on CoreWeave GPUs, wrote and embedded the descriptions. YOLO, on those same NVIDIA GPUs, is what the coach watches: the boxes pick the frame, the spotlight, and the sentence. We built Behind in Cursor with SpaceXAI. Weights & Biases serverless inference, from CoreWeave, is there for a written coaching note. The film takes its spoken line from the YOLO tracks, so the voice and the spotlight show the same thing.
 SpaceXAI (Cursor)
 CoreWeave (Weights & Biases)
 NVIDIA