CityPulse turns urban video archives into an interactive visual storytelling agent.
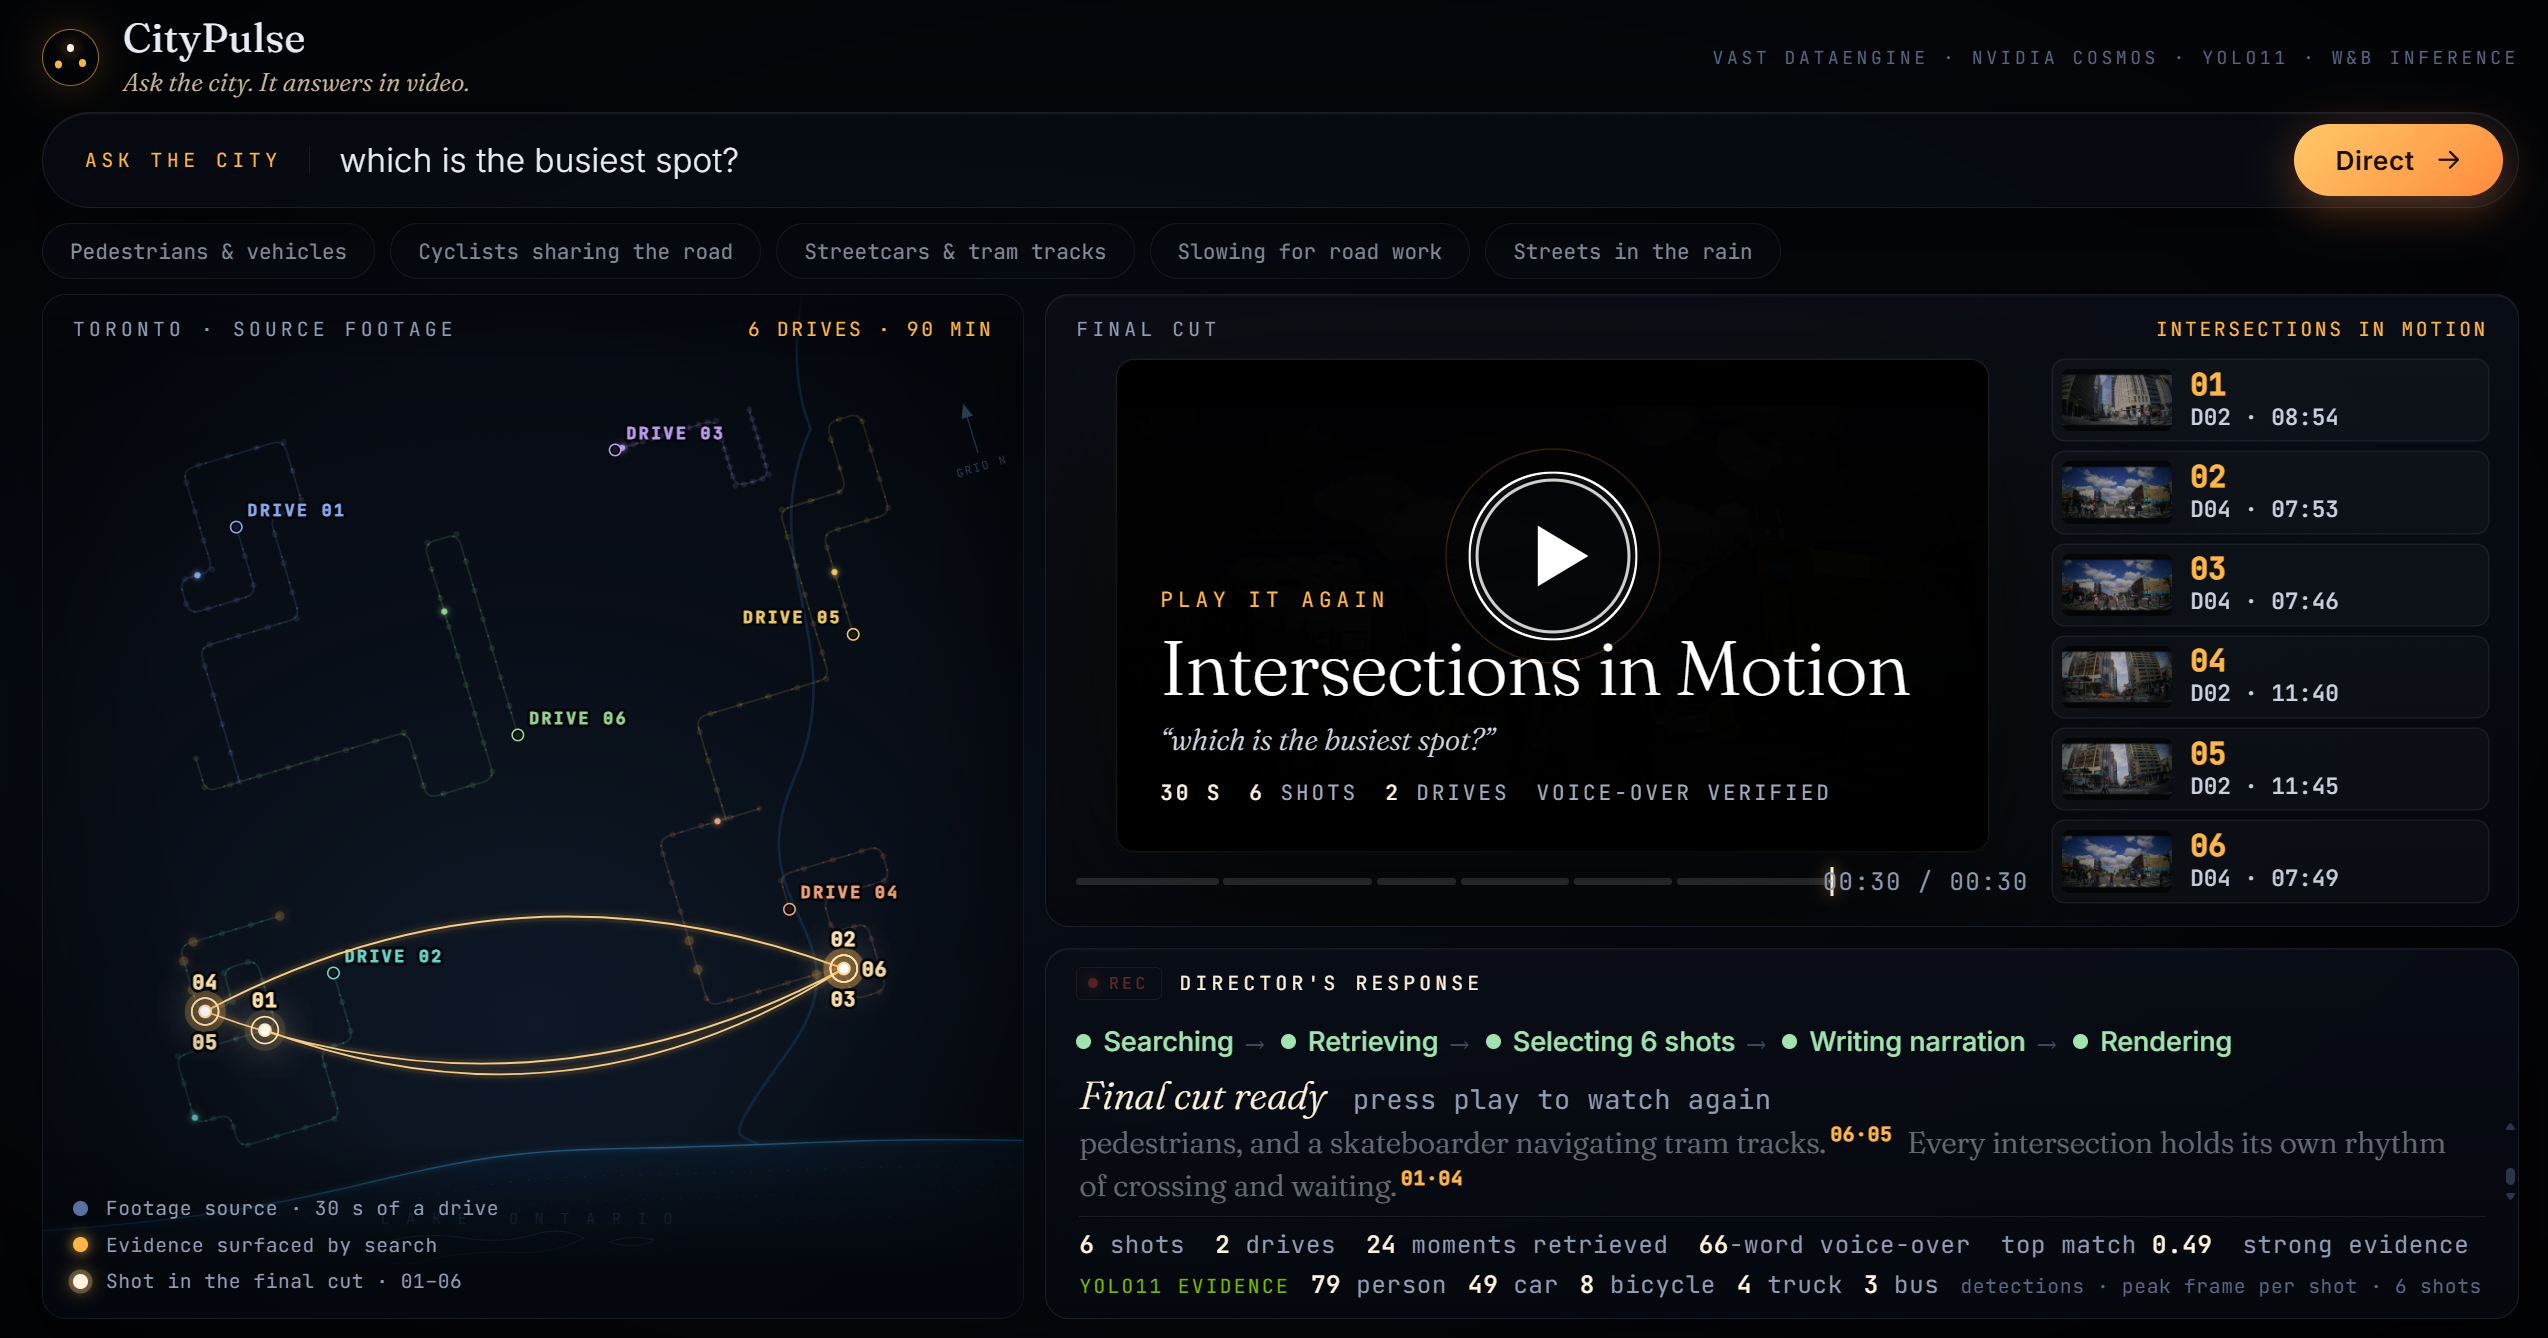
A user asks a question such as “How do pedestrians and vehicles interact at Toronto intersections?” CityPulse searches the indexed Toronto driving footage, surfaces the strongest evidence, selects six complementary shots, writes a grounded narration, and automatically edits them into a 30-second narrated film.
The interface makes the agent’s work visible: source routes illuminate as relevant moments are found, evidence clips appear during retrieval, selected shots are ordered into the final cut, and the resulting film answers the original question.
CityPulse builds directly on the VAST Video Search & Summary stack. VAST DataEngine stores and retrieves the indexed video evidence. NVIDIA Cosmos Embed powers semantic video retrieval, while Cosmos Reason provides scene understanding and descriptions. YOLO11 detections provide object-level evidence for vehicles, pedestrians, cyclists and other road users. Weights & Biases serverless inference on CoreWeave powers the higher-level AI director that selects shots and writes the narration.
The final response is not generated footage: every shot comes from the licensed source archive and remains grounded in retrieved evidence.