tokens&
BrowseFor enterprises
tokens&

Find tools, check provider offers, save a build plan, and share your work when you’re ready.

For buildersFor enterprises

For builders

  • Startup credits and perks
  • Agent Skills
  • Publish a project

For enterprises

  • Start free company workspace
  • Submit a tool, product, or perk

Community

  • Community
  • Newsletter
  • Events
Xin

© 2026 tokensand, LLC. All rights reserved.

  • Terms
  • Privacy
  • Security
  • Data Processing
  • Status
  1. Hackathon
  2. Project gallery
  3. Last Seen (Spatial Intelligence)
Darshan Chhedaabout 10 hours agoContributorJudging locked: Event build

Last Seen (Spatial Intelligence)

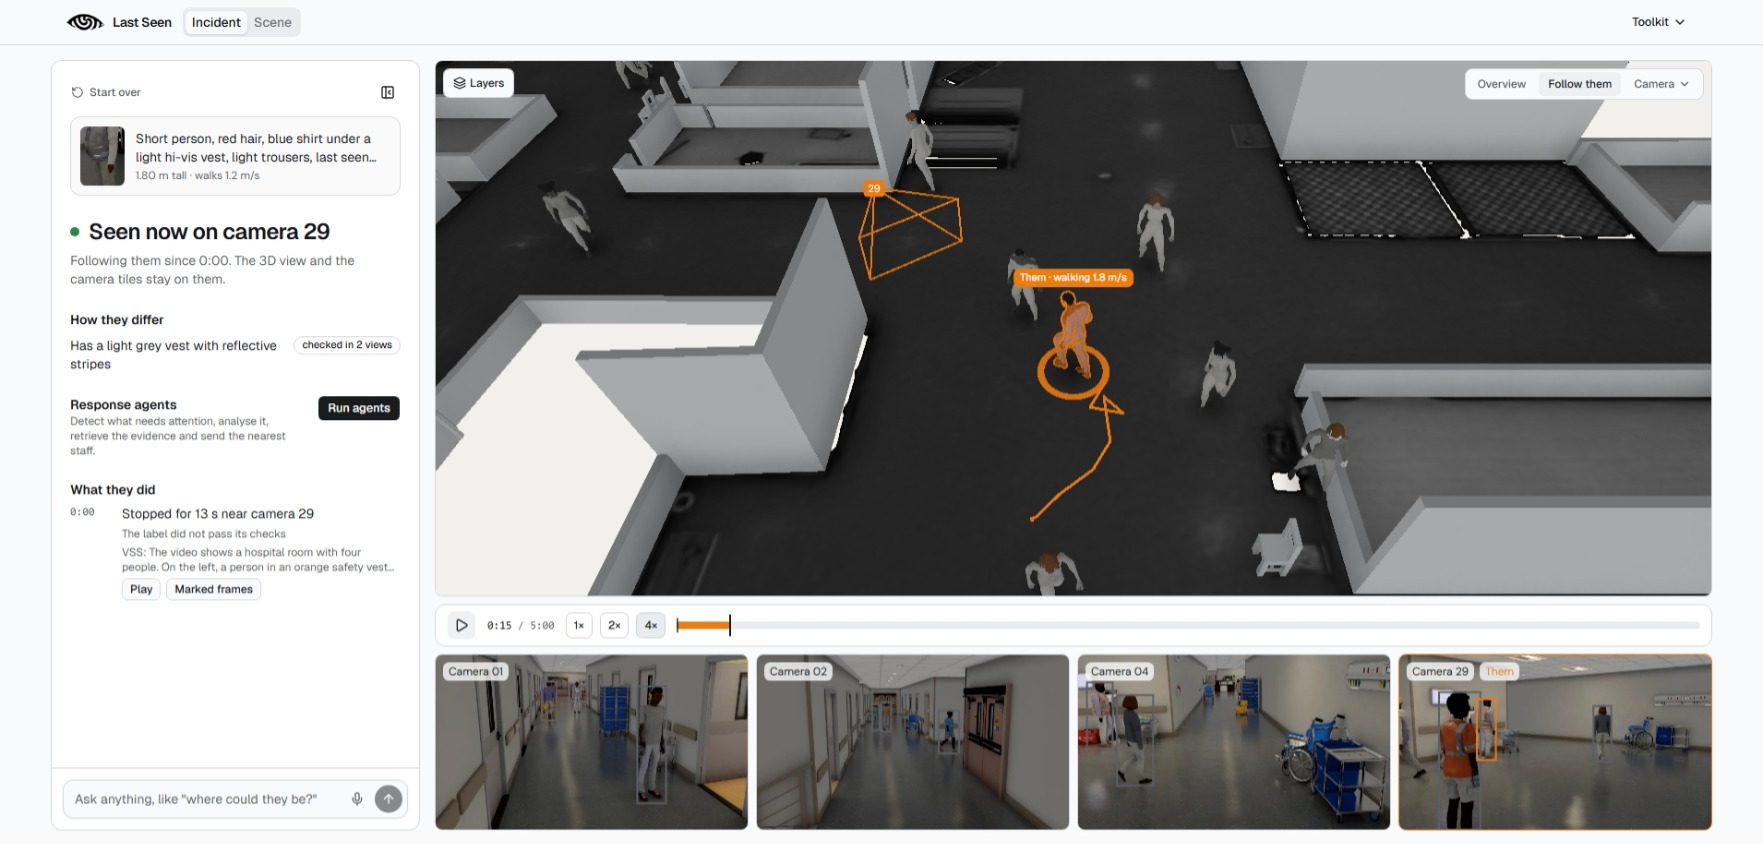
When a patient with dementia walks off a ward, CCTV can only say where they were last seen, so LastSeen lets hospital staff describe the person, finds and follows them across every camera, and when they slip out of view, shows where they could be now and where to look first.

Review the project

Start with the source code, then open the demo or video if available.

View GitHub repository
Visit project websiteWatch demo videoProject gallery
Demo video
Watch demo video
Project description
Last Seen is a search tool for the first few minutes after someone goes missing inside a building. A member of staff describes the person out loud, and Last Seen searches every camera, shows the people who fit, and asks a quick question when two of them look alike, so the right person gets picked instead of guessed. From there it follows them across cameras on a 3D model of the building. When they walk somewhere no camera covers, it shows how far they could have got, clears the areas the cameras can see are empty, and ranks the cameras and rooms worth checking first, until a camera picks them up again and confirms it is the same person. We built it on NVIDIA’s synthetic hospital footage and used only half of the cameras, keeping the rest hidden so we could check our guesses against where people really were. The footage runs through the VAST DataEngine pipeline into VastDB, which holds the video search index, our tracks and our person index. NVIDIA Cosmos Reason describes each person and checks what it says against two camera views, Cosmos Embed matches descriptions to people, YOLO11 finds people in each frame, and Canary turns speech into the search. Weights & Biases serverless inference runs the agent’s reasoning, Weave traces and scores every step, CoreWeave GPUs serve the models, and we built the whole thing in Cursor.
Project links
  • GitHub repository
  • Project website
  • Demo video
Tools used
  • VAST Data logoVAST Data
  • SpaceXAI (Cursor) logoSpaceXAI (Cursor)
  • CoreWeave (Weights & Biases) logoCoreWeave (Weights & Biases)
  • NVIDIA logoNVIDIA
  • Tokens& logoTokens&
Tools used
  • VAST Data logoVAST Data
  • SpaceXAI (Cursor) logoSpaceXAI (Cursor)
  • CoreWeave (Weights & Biases) logoCoreWeave (Weights & Biases)
  • NVIDIA logoNVIDIA
  • Tokens& logoTokens&