tokens&
BrowseFor enterprises
tokens&

Find tools, check provider offers, save a build plan, and share your work when you’re ready.

For buildersFor enterprises

For builders

  • Product launches
  • Builder projects
  • Startup credits and perks
  • Agent Skills
  • Published agents
  • API and agent docs
  • Publish a project

For enterprises

  • Start free company workspace
  • Submit a tool, product, or perk

Community

  • Community
  • Newsletter
  • Events
Xin

© 2026 tokensand, LLC. All rights reserved.

  • Terms
  • Privacy
  • Security
  • Data Processing
  • Status
  1. Hackathon
  2. Project gallery
  3. Lethe- forgetfulness
Anonymous builderabout 1 month agoJudging locked: Event build

Lethe- forgetfulness

Lethe is an agent runtime with expiring memory. It keeps one small state object it rewrites itself, gives every fact a TTL, and never lets raw web pages into the prompt. Demo: a pricing agent watching the live RV market for hours with a context that never grows.

Community votes recognize the build and do not affect official judging.

Review the project

Start with the source code, then open the demo or video if available.

View GitHub repository
Visit project websiteWatch demo videoProject gallery
Demo video
Watch demo video
Project description
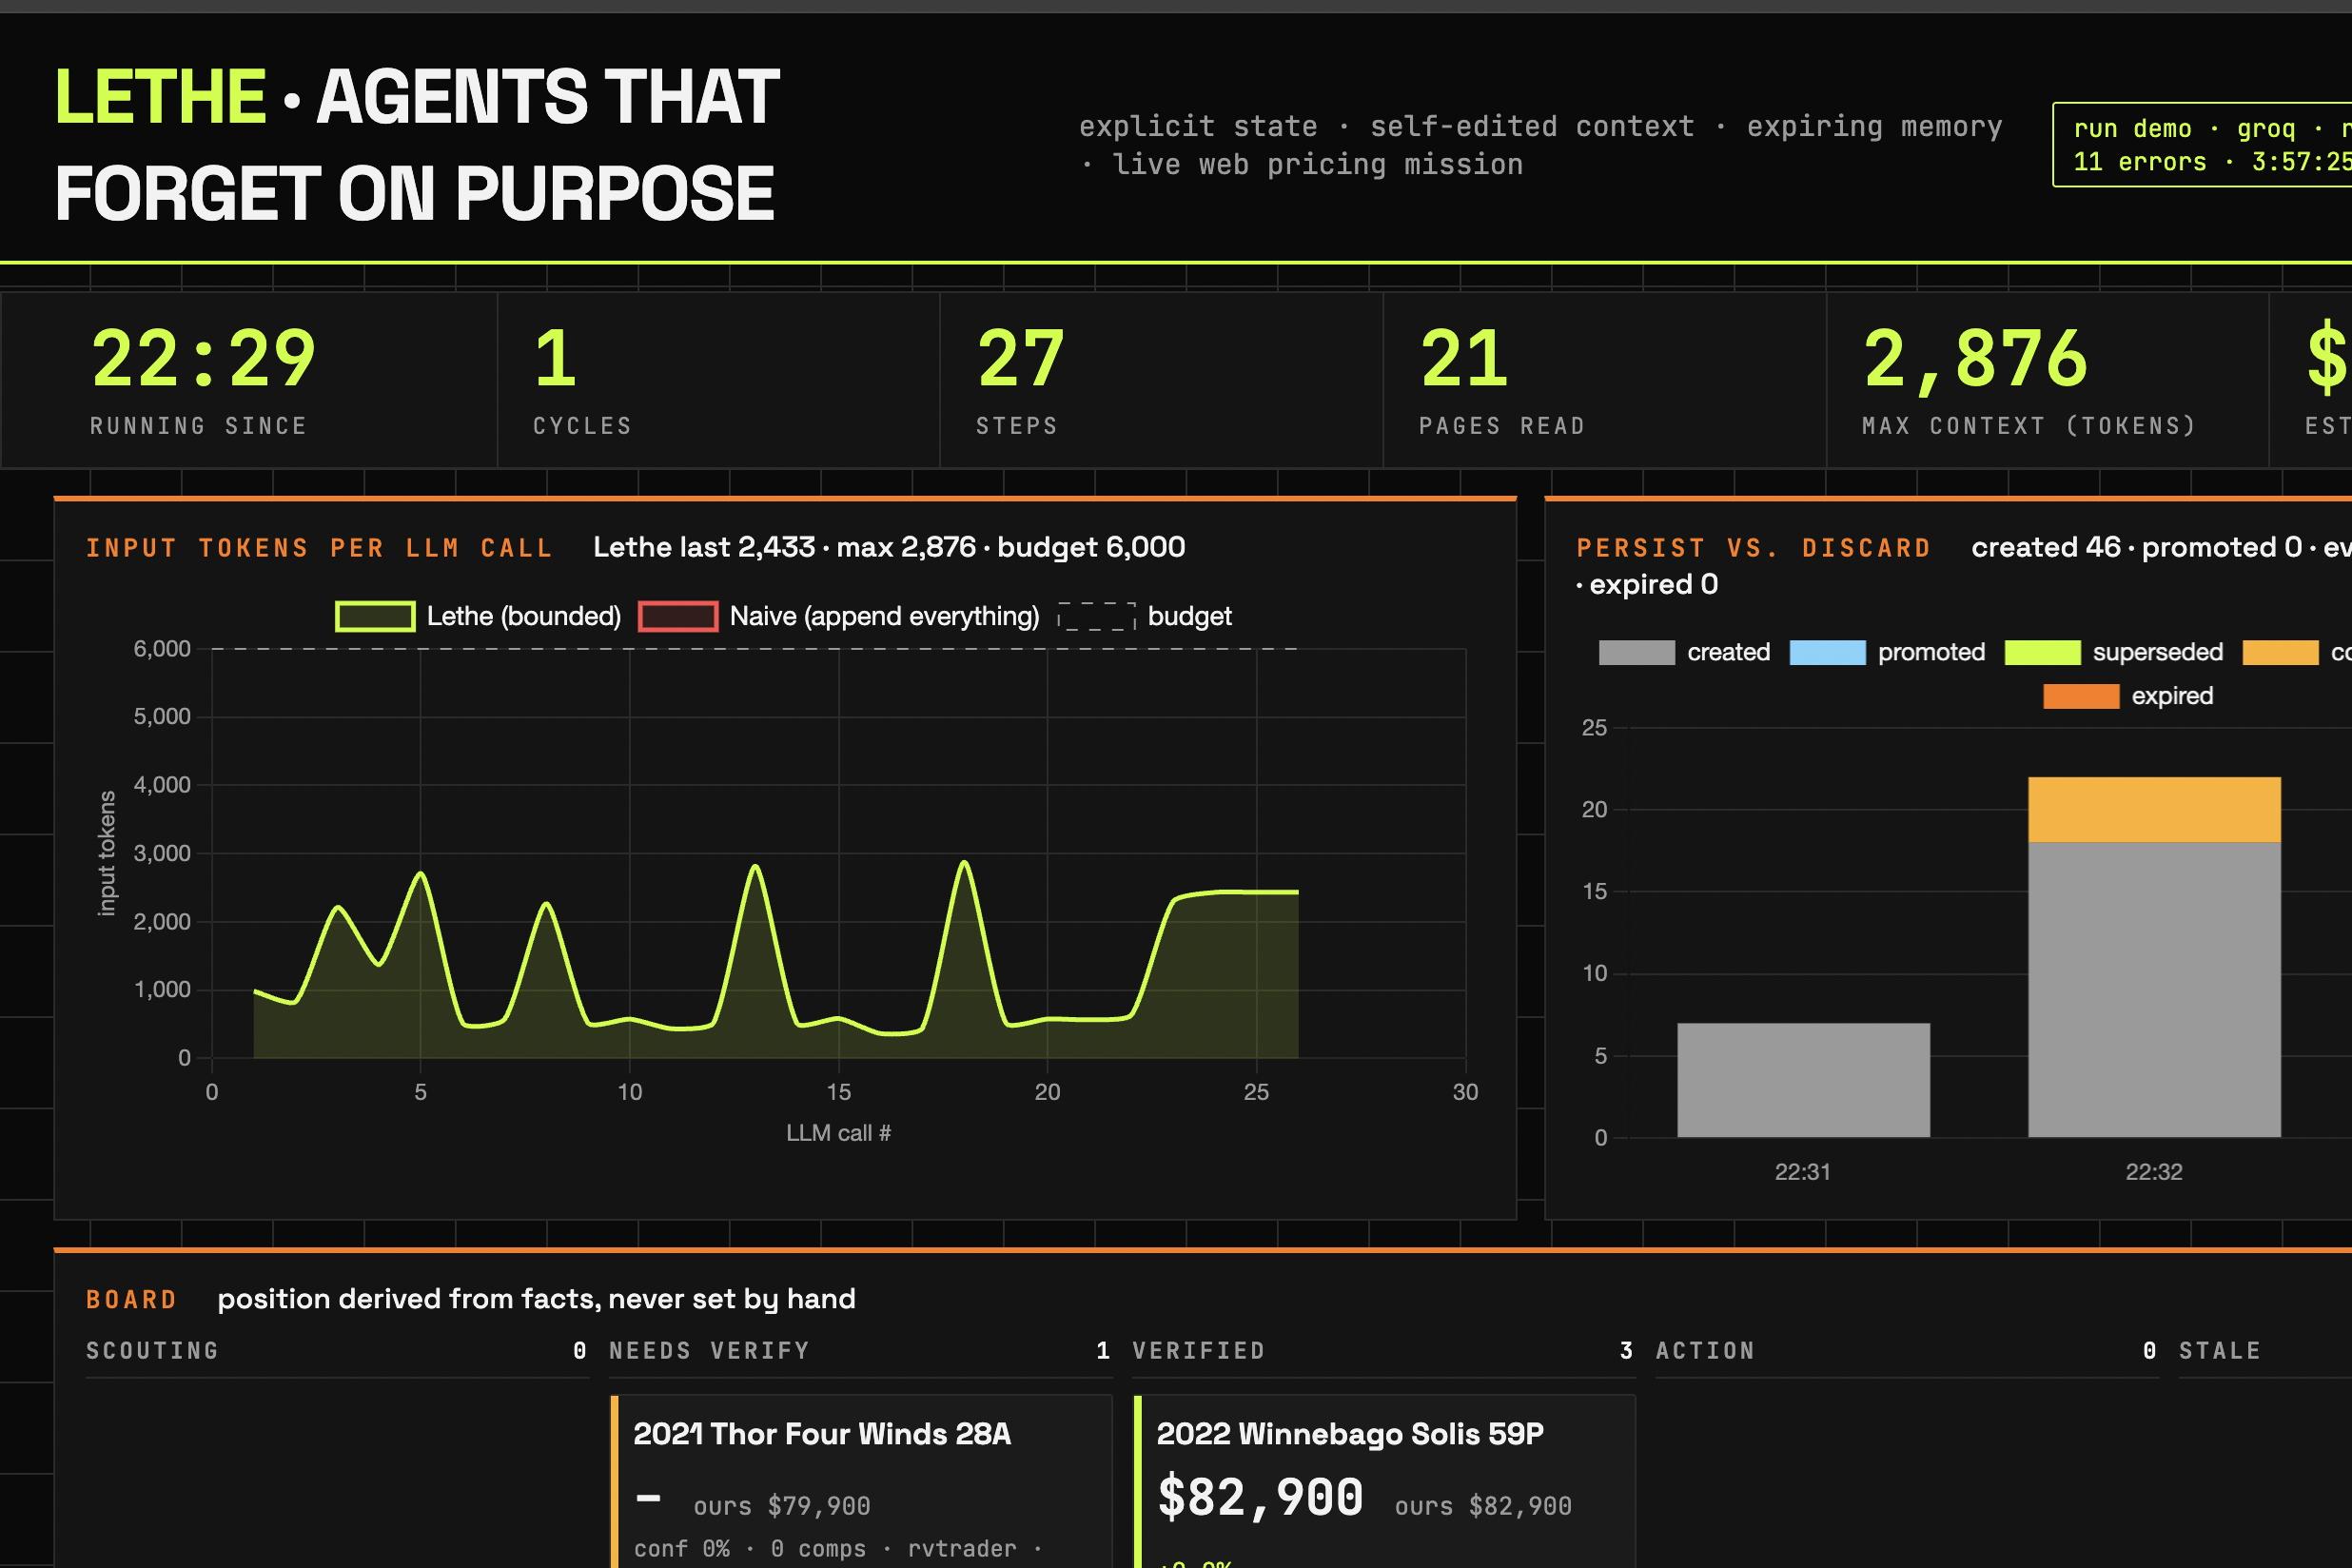
Long-horizon agents drown in their own history: every observation gets appended, every call gets slower and costlier, and stale context corrupts decisions. Lethe fixes this with three rules. (1) Explicit mutable state: a one-page Mission Ledger the agent rewrites every cycle instead of a transcript, with a hard 6k-token cap per LLM call. (2) The agent edits its own context through tools: update_plan, record_decision, add_lesson, set_recommendation, mark_stale. (3) A clear split between persist and discard: raw pages die with the worker that read them, extracted facts carry a TTL, facts confirmed by two sources persist, and a sold listing wipes everything about it. The demo mission prices a dealership's used RVs against the live web. Scouts use Nimble to search and read listings and return a card under 200 tokens. A Liquid LFM2.5 model running locally on a laptop assigns every fact its TTL and confidence. An Auditor checks comparability and, when a strategy fails, writes a lesson and the agent switches strategy on its own. OpenAI's gpt-oss models plan and decide. All state and every event, including token counts per call, live in a RawTree database, so kill -9 followed by restart resumes in under a second with no replay. Results: max context 2,876 tokens over hours of live runs. The naive baseline (same tools, append-everything) hits the provider's wall by step 6. The dashboard shows both lines, the board, the facts being expired and contradicted, and the self-corrections.
Project links
  • GitHub repository
  • Project website
  • Demo video
Tools used
  • Nimble logoNimble

    Event resource · Developer docs

    Sign in to visit
  • Tinybird logoTinybird

    Event resource · RawTree developer docs

    Sign in to visit
  • Liquid AI logoLiquid AI

    Event resource · Models on Hugging Face

    Sign in to visit
  • Codex logoCodex
    No link provided