Long-running agents either keep every old note in context (slow, costly, noisy) or delete it and lose the reasoning. Memory on Alarm, built on our SPORE engine, adds a third option: "forget until."
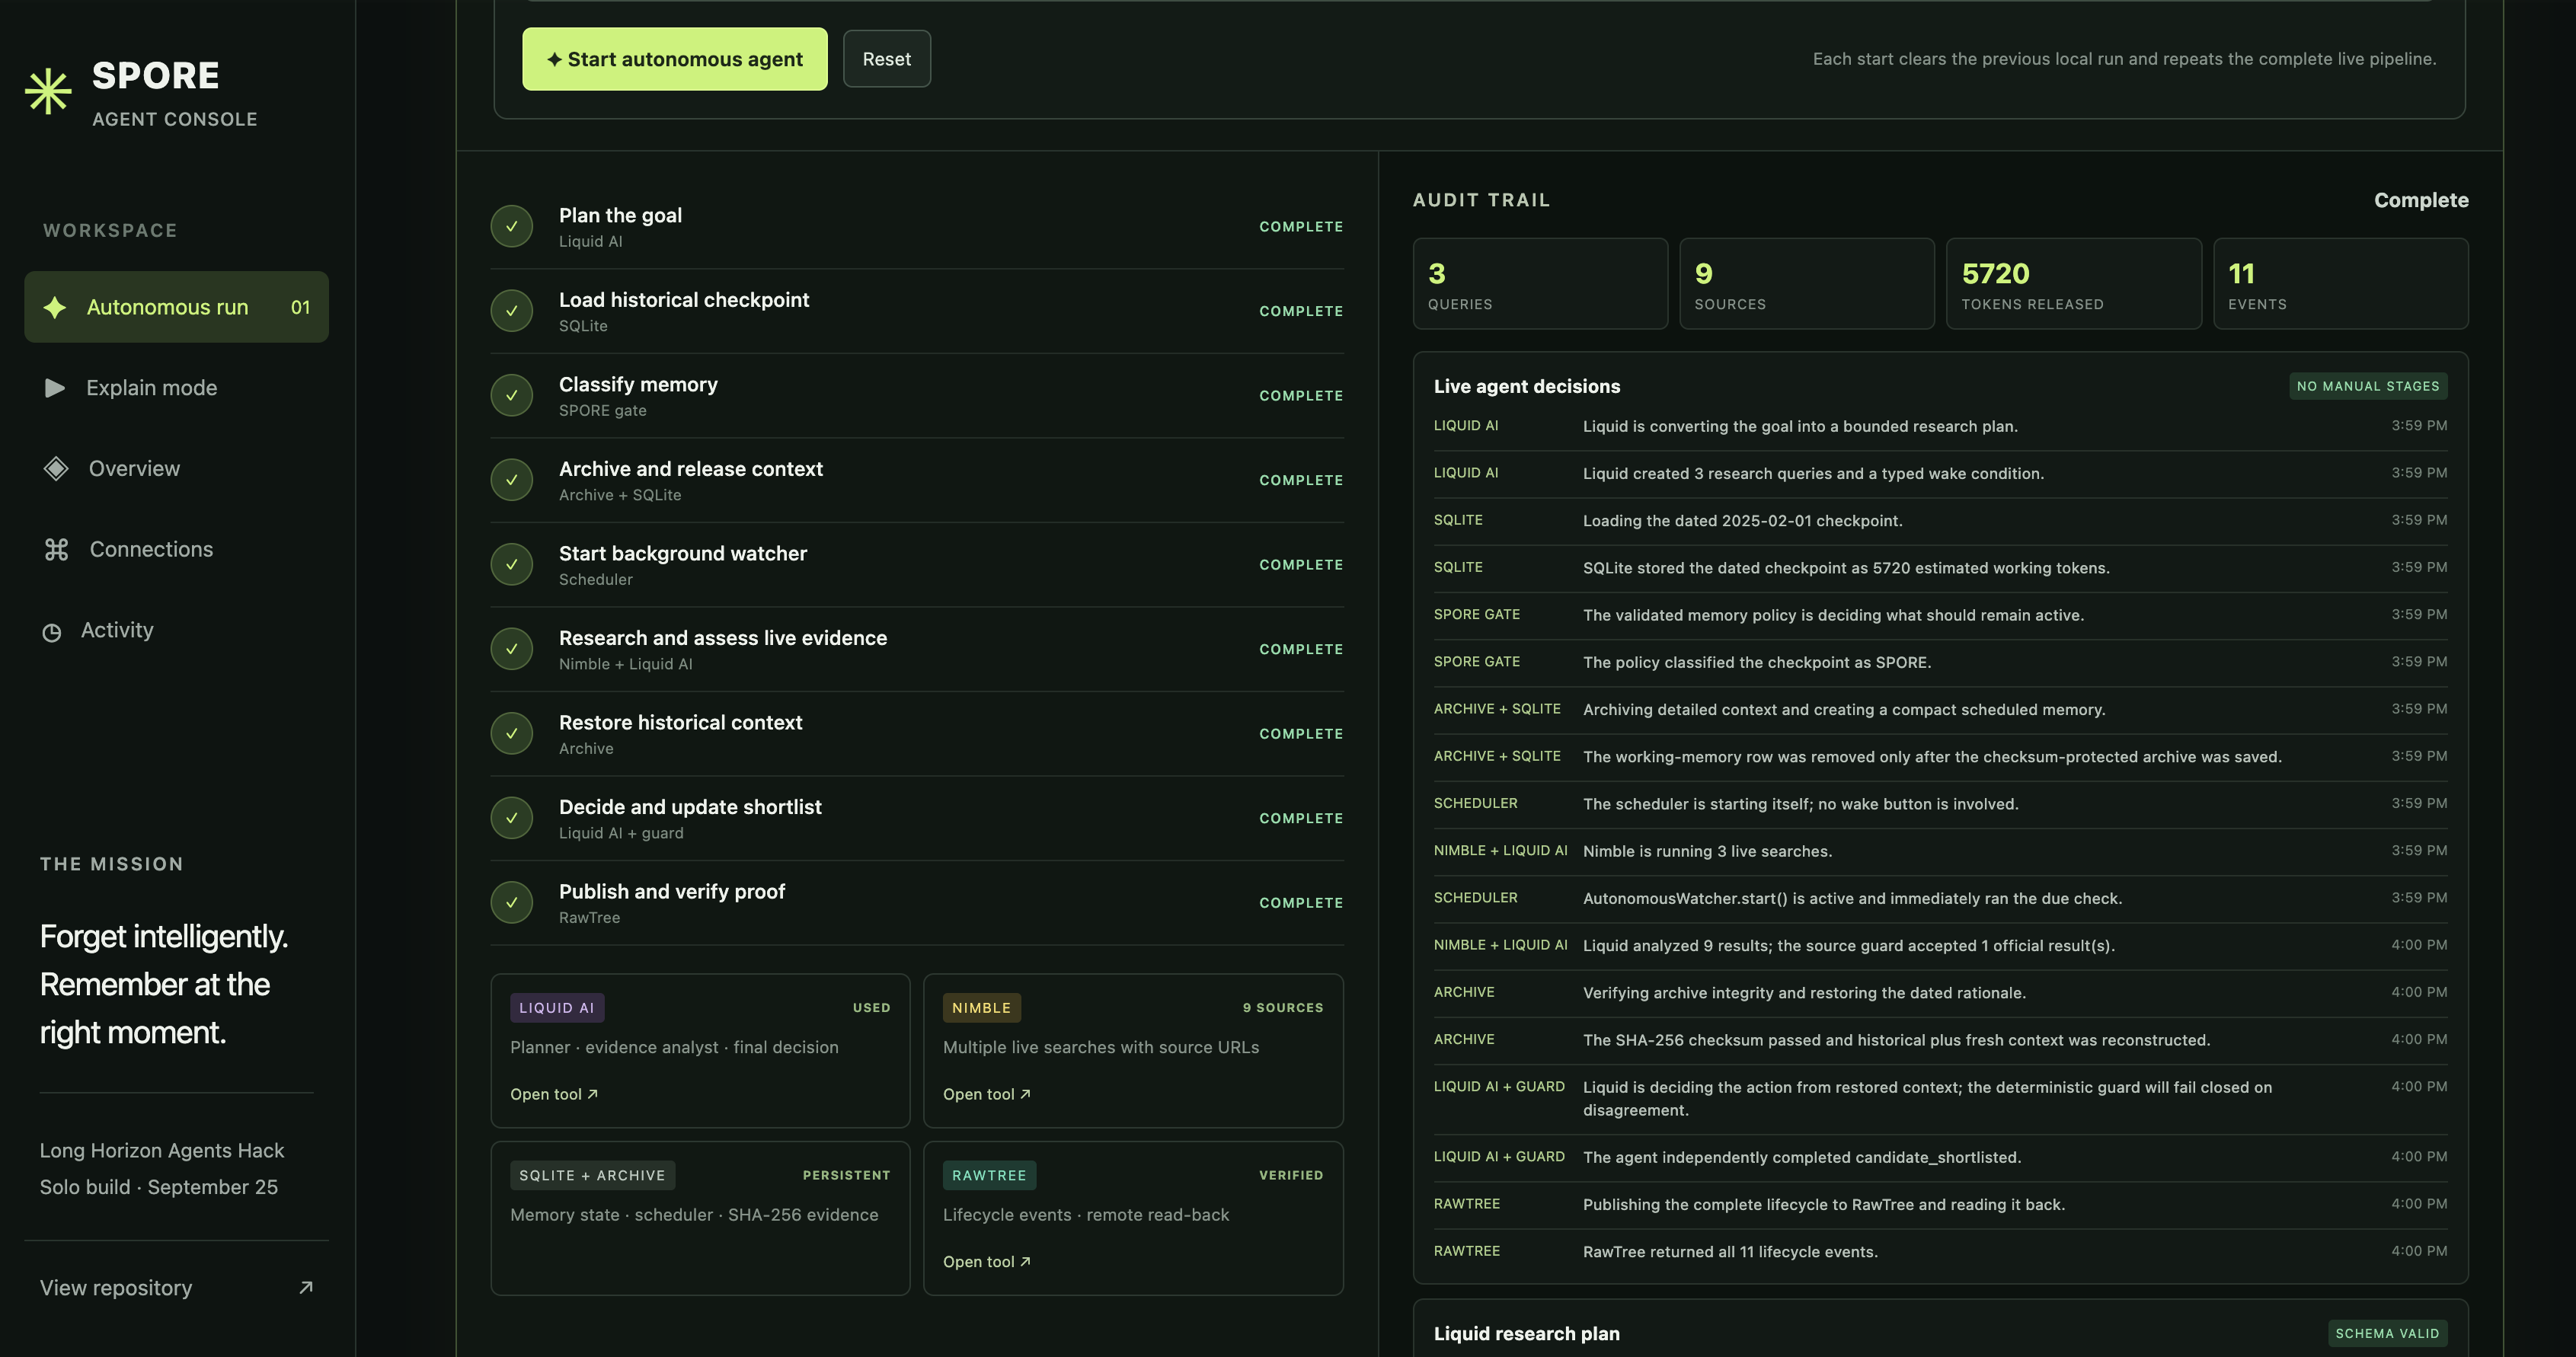
How it works: from one goal, the agent plans its research, classifies each observation as ACTIVE, DURABLE, SPORE or DISCARD, and turns temporarily blocked findings into a SPORE. The full evidence goes to a SHA-256-checked archive and leaves working memory. Only a small reminder remains: the exact wake condition, a search query and a schedule. A watcher starts itself (no wake button), checks the live web, and when the condition becomes true it wakes the memory once, restores the original reasoning, combines it with fresh evidence, re-decides, and updates the shortlist.
Tools:
• Liquid AI (LFM2.5-8B, local via Ollama): plans the research, judges live evidence with cited sources, makes the post-wake decision. Every output is schema-validated, and a deterministic guard blocks disagreement.
• Nimble: live web searches for the watcher, with inspectable source URLs.
• RawTree / Tinybird: external audit log; all 11 lifecycle events are written and read back to prove they were stored.
Verified run: