tokens&
BrowseFor enterprises
tokens&

Find tools, check provider offers, save a build plan, and share your work when you’re ready.

For buildersFor enterprises

For builders

  • Product launches
  • Builder projects
  • Startup credits and perks
  • Agent Skills
  • Published agents
  • API and agent docs
  • Publish a project

For enterprises

  • Start free company workspace
  • Submit a tool, product, or perk

Community

  • Community
  • Newsletter
  • Events
Xin

© 2026 tokensand, LLC. All rights reserved.

  • Terms
  • Privacy
  • Security
  • Data Processing
  • Status
  1. Hackathon
  2. Project gallery
  3. Memory on Alarm
Anonymous builderabout 1 month agoJudging locked: Event build

Memory on Alarm

Memory on Alarm lets long-running AI agents put old research to sleep, watch the live web for the one change that matters, and automatically wake that memory to act again, instead of carrying stale context forever or forgetting it.

Community votes recognize the build and do not affect official judging.

Review the project

Start with the source code, then open the demo or video if available.

View GitHub repository
Visit project websiteWatch demo videoProject gallery
Demo video
Watch demo video
Project description
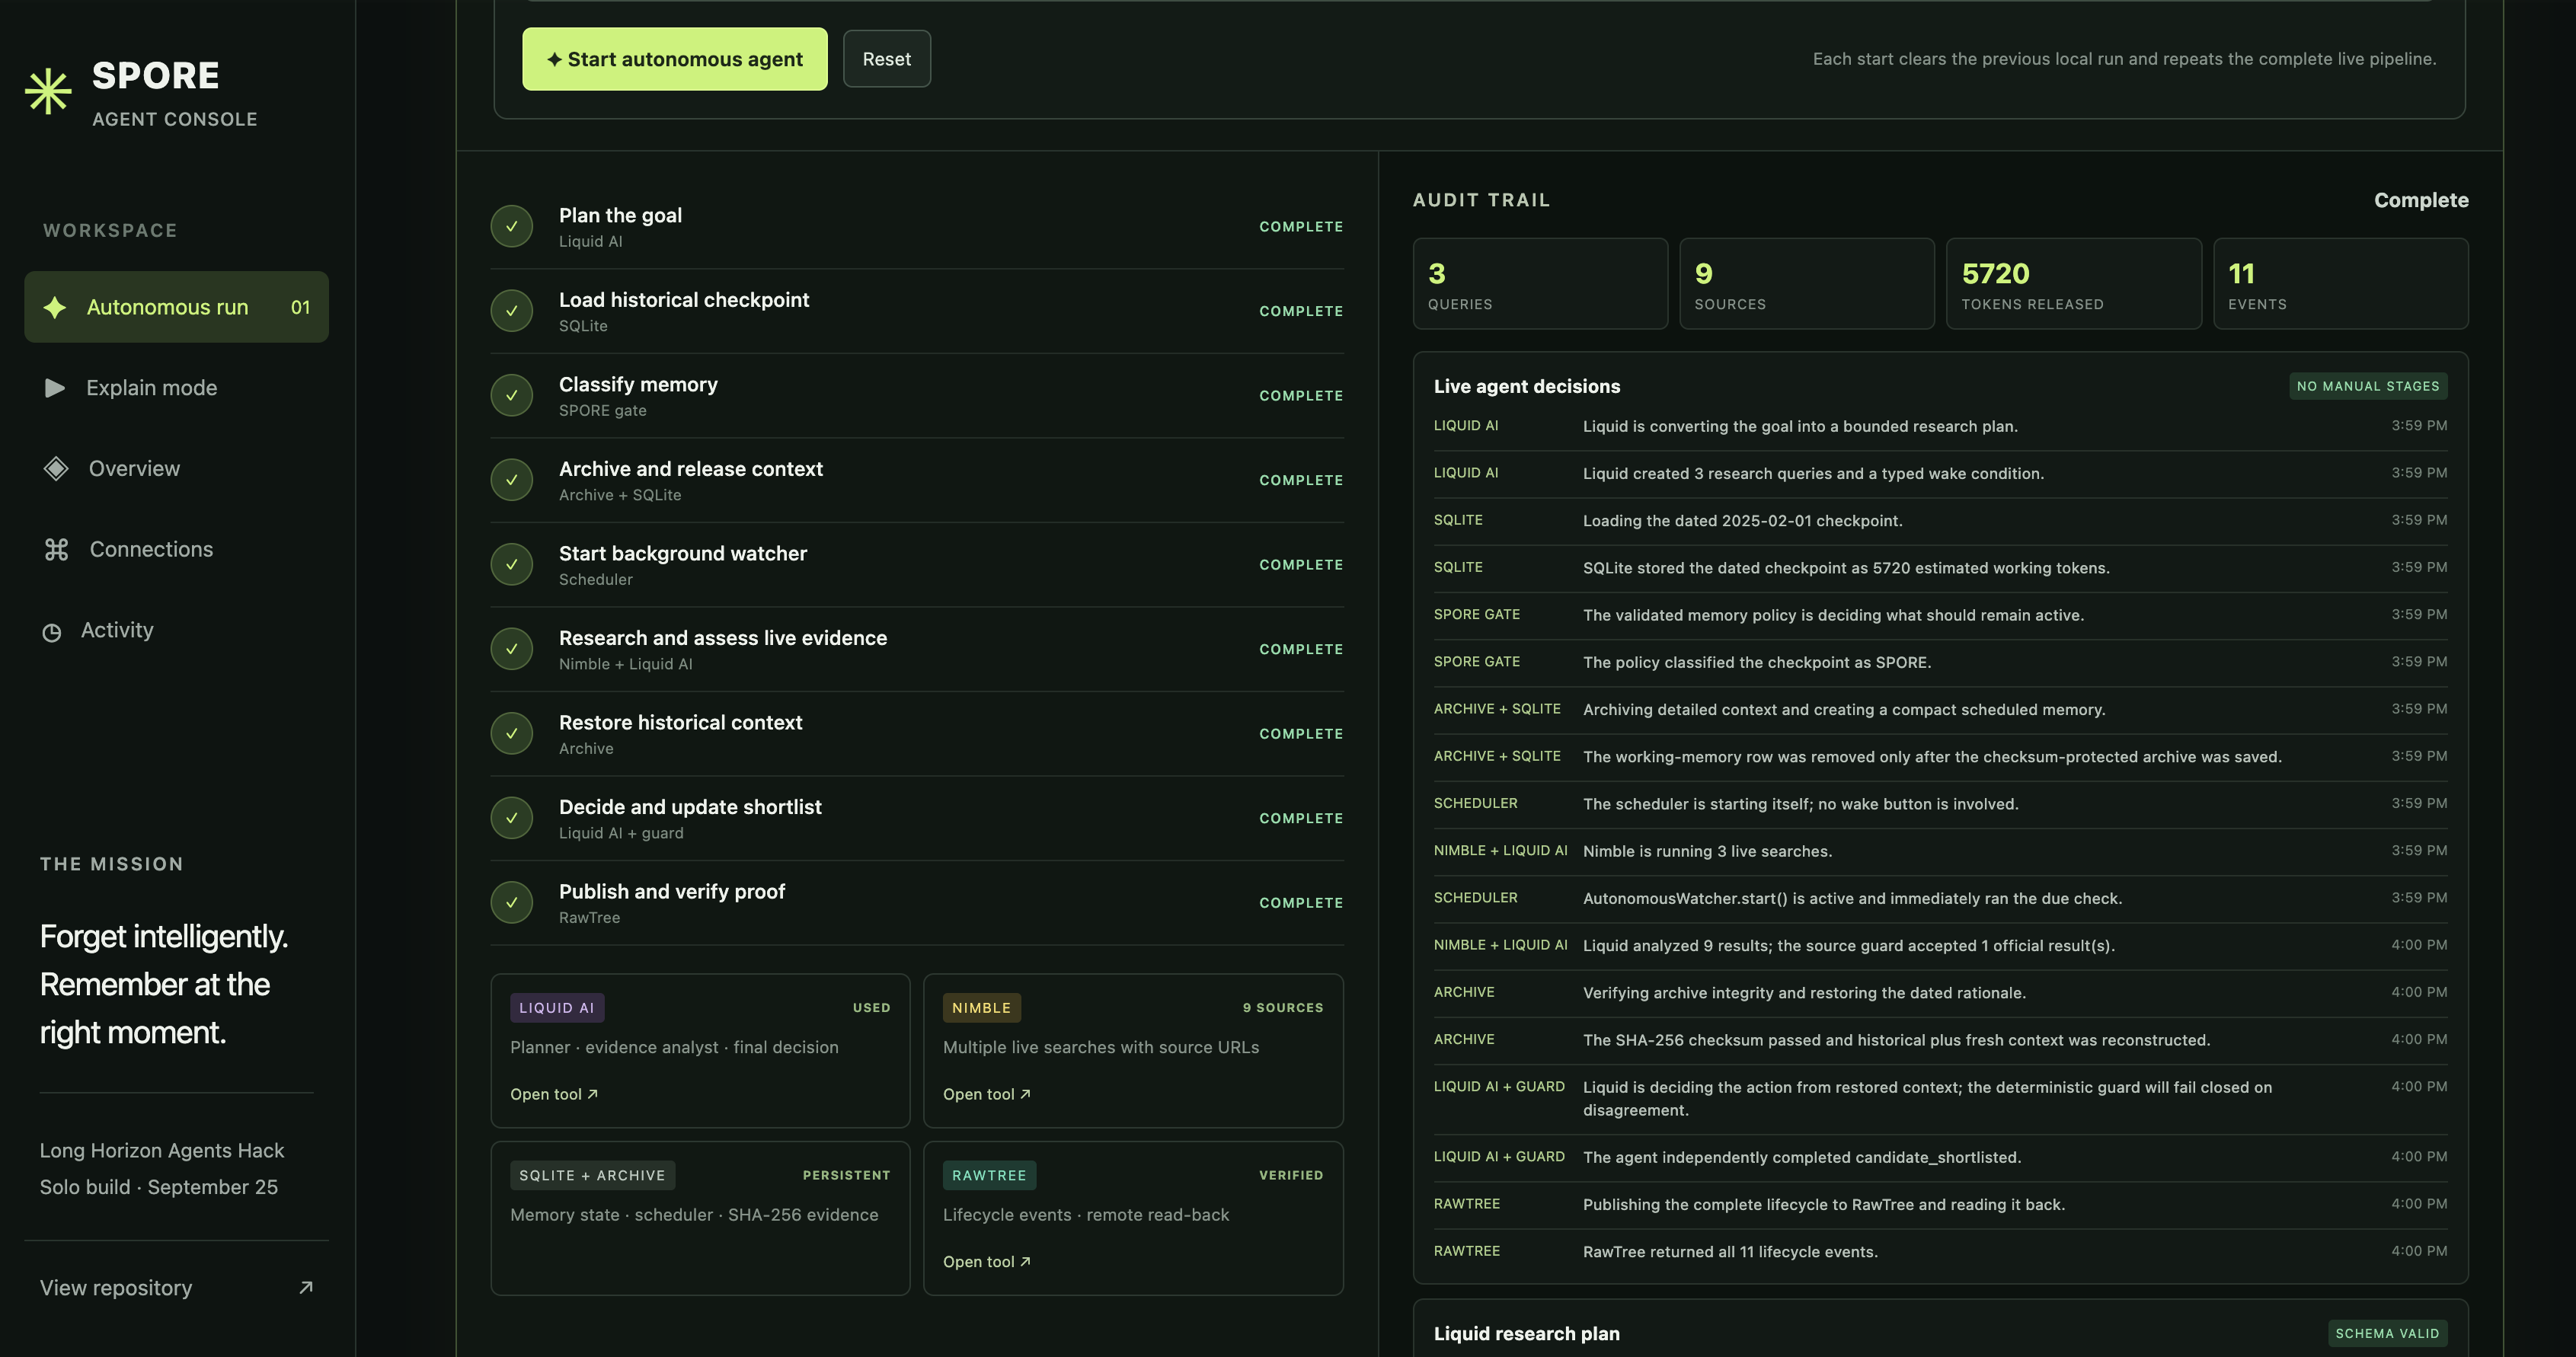
Long-running agents either keep every old note in context (slow, costly, noisy) or delete it and lose the reasoning. Memory on Alarm, built on our SPORE engine, adds a third option: "forget until." How it works: from one goal, the agent plans its research, classifies each observation as ACTIVE, DURABLE, SPORE or DISCARD, and turns temporarily blocked findings into a SPORE. The full evidence goes to a SHA-256-checked archive and leaves working memory. Only a small reminder remains: the exact wake condition, a search query and a schedule. A watcher starts itself (no wake button), checks the live web, and when the condition becomes true it wakes the memory once, restores the original reasoning, combines it with fresh evidence, re-decides, and updates the shortlist. Tools: • Liquid AI (LFM2.5-8B, local via Ollama): plans the research, judges live evidence with cited sources, makes the post-wake decision. Every output is schema-validated, and a deterministic guard blocks disagreement. • Nimble: live web searches for the watcher, with inspectable source URLs. • RawTree / Tinybird: external audit log; all 11 lifecycle events are written and read back to prove they were stored. Verified run: 5,720 working-context tokens released, 9 live sources, memory woken automatically, candidate shortlisted, 11/11 events verified. 52 automated tests.
Project links
  • GitHub repository
  • Project website
  • Demo video
Tools used
  • Codex logoCodex
    No link provided
  • Liquid AI logoLiquid AI

    Event resource · Models on Hugging Face

Sign in to visit
  • Nimble logoNimble

    Event resource · Developer docs

    Sign in to visit
  • Tinybird logoTinybird

    Event resource · RawTree developer docs

    Sign in to visit