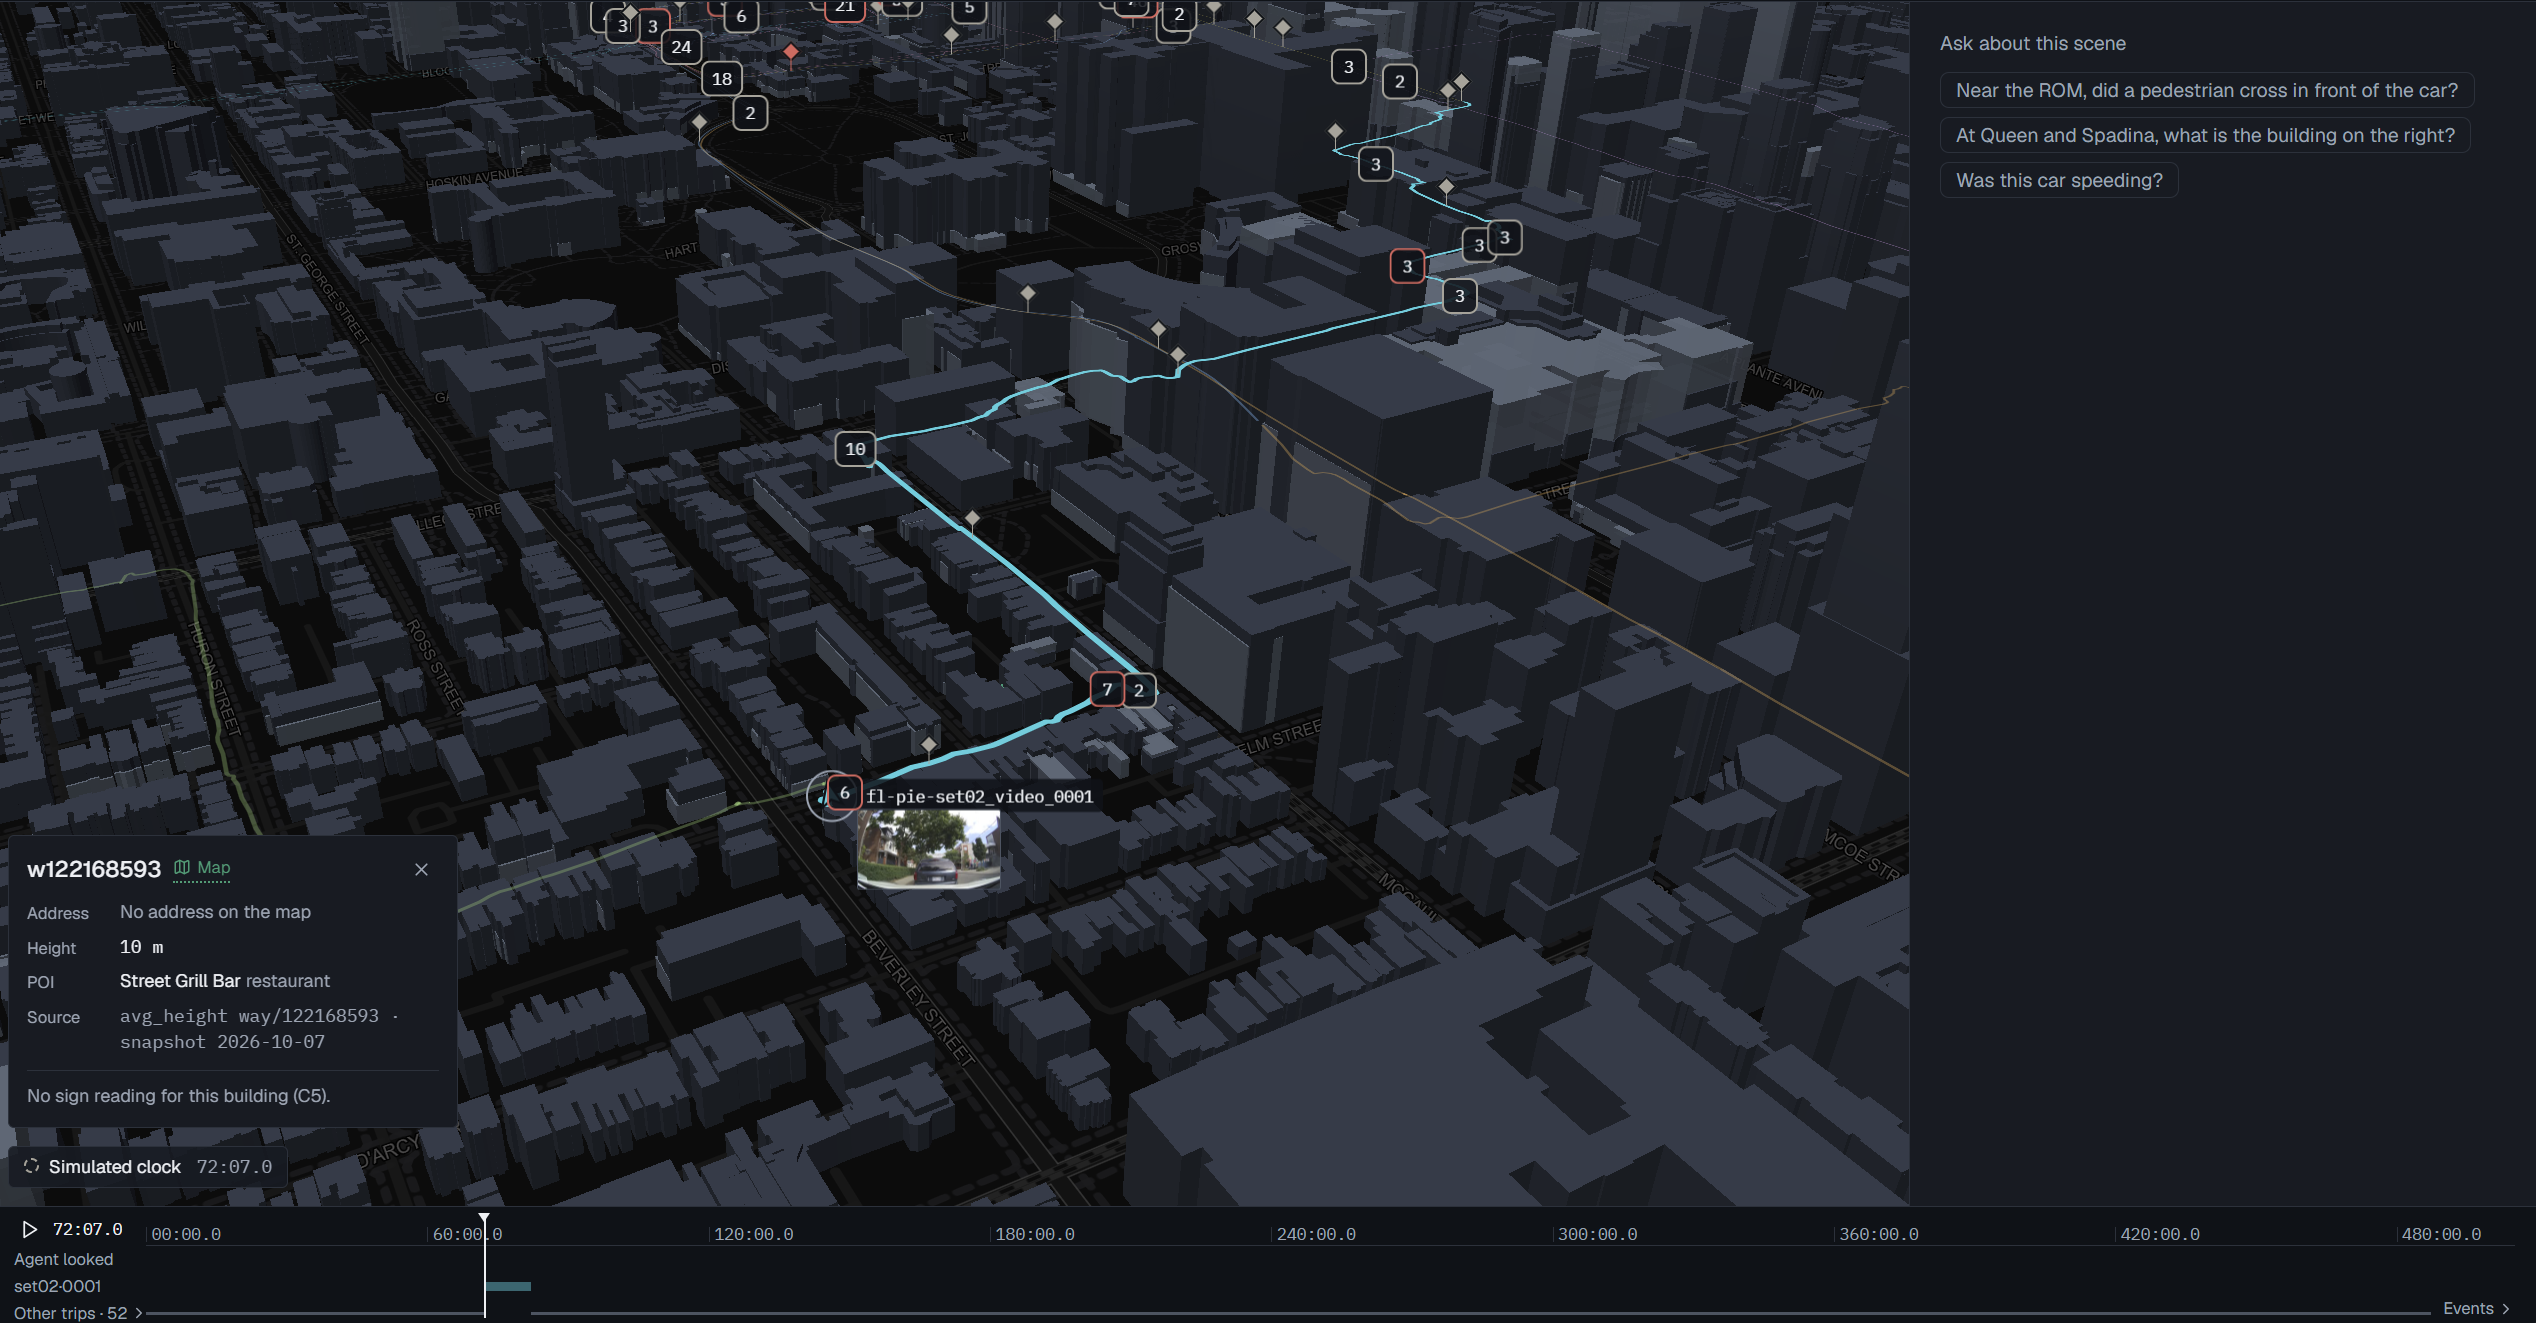
Spatial Video Agent answers one plain-English question across every camera in the corpus: 3,537 clips from warehouses, a Toronto dashcam, and New York and San Francisco street corners. For each hit, it runs tracking and geometry at query time and returns an answer card grouped by evidence level. Where a camera has calibration or GPS, the card shows the person-to-vehicle distance in meters with an uncertainty. Where it has neither, the agent abstains and says “no geometry”. Video and detections live in VAST S3, and captions and Cosmos embeddings are read live from VastDB on every query. NVIDIA Cosmos 3 Reason and Cosmos-Embed1 run on CoreWeave GPUs. Our FastAPI app runs on the CoreWeave cluster. W&B Weave traces every agent step. Every number comes from CV and geometry, not from the model.
 SpaceXAI (Cursor)
 CoreWeave (Weights & Biases)
 NVIDIA